
An AI writes GPU kernels for Apple Silicon. A judge it can't fool decides what's real.
The winners go into a real model.

AI can write GPU kernels now, and the papers are full of "3× faster". A lot of it doesn't survive a second look:
- A one-shape
allclosecheck, the KernelBench standard, misses 78.6% of precision bugs (Measuring the Checker). - A speedup reported as 1.43× was 0.88× on inputs the model hadn't seen (KernelBench-Verified).
- On Apple Metal, 30% of LLM "wins" broke on a config nobody tested (Gaming Without an Attacker).
Writing kernels is cheap now. Trusting them is the hard part. I built carmen to learn how kernels work and to answer one question honestly: can an AI make a model on my Mac faster, with proof?
On a real model, yes, by a little. carmen's AI wrote two fused 4-bit kernels that replace 8 MLX kernels with 2 in every layer of Qwen 2.5 0.5B. Decode got 3% faster, with identical output.
| Qwen 2.5 0.5B (4-bit), M4, decode | vs stock MLX | answers |
|---|---|---|
mx.compile alone |
1.00× [1.00–1.01] | identical |
| carmen's kernels | 1.03× [1.02–1.05] | identical 256 tokens |
30 paired turns, 95% bootstrap range. carmen e2e --modes stock,compile,mlp+compile --repeats 30 --gen 256
On single kernels, it wins where MLX runs several kernels and ties where Apple wrote one.
| kernel | vs MLX | vs mx.compile |
|---|---|---|
| masked_softmax (MLX: 3 kernels) | 1.82× | 1.38× |
| add_rmsnorm (MLX: 2 kernels) | 1.41× | 1.43× |
| mlp_down, 4-bit, Qwen's shape (MLX: 2 kernels) | 1.02× | 1.06× |
| softmax · rmsnorm · layernorm (MLX: 1 tuned kernel) | 0.95–0.99× | |
| matmul · attention (MLX: heavily tuned) | 0.93× · 0.54× |
The judge caught all 75 bugs planted in seven kernels. A KernelBench-style check let 35 of them through. How the judge works →
- AI kernels don't beat hand-tuned code. They beat code nobody fused.
- A kernel that wins alone can lose inside a model. One scored 1.15× in the judge and made Qwen 18% slower: it was timed
at the wrong shapes, against a weak baseline, one launch at a time. Now
carmen run <op> --for qwen0.5bjudges at the model's real shapes and number format, againstmx.compile, and checks the winner inside the model at the end (ideas from SoL-Pi). - Measuring honestly took more work than writing kernels. Running versions one after another, instead of taking turns, produced two "wins" (+40% prefill, 1.09× decode) that weren't real. A browser in the background swung speed by ±27%.
- Small models on a Mac are launch-bound. Qwen 0.5B reads 0.28 GB of weights per word, so the M4 could do ~346 tok/s. Stock MLX reaches 51%. The rest is hundreds of tiny kernel launches per word. Bigger fused kernels are the way forward.
New to kernels? How it all works explains LLMs, GPUs and kernels from scratch.
- Carmy (the model) writes the kernel. It's trusted to be smart and never trusted to grade. It can only return text.
- The judge is plain Python. It checks every kernel against a float64 answer key on hundreds of inputs, including secret ones drawn fresh every round, races it against MLX, and says where a kernel is wrong, not just that it is.
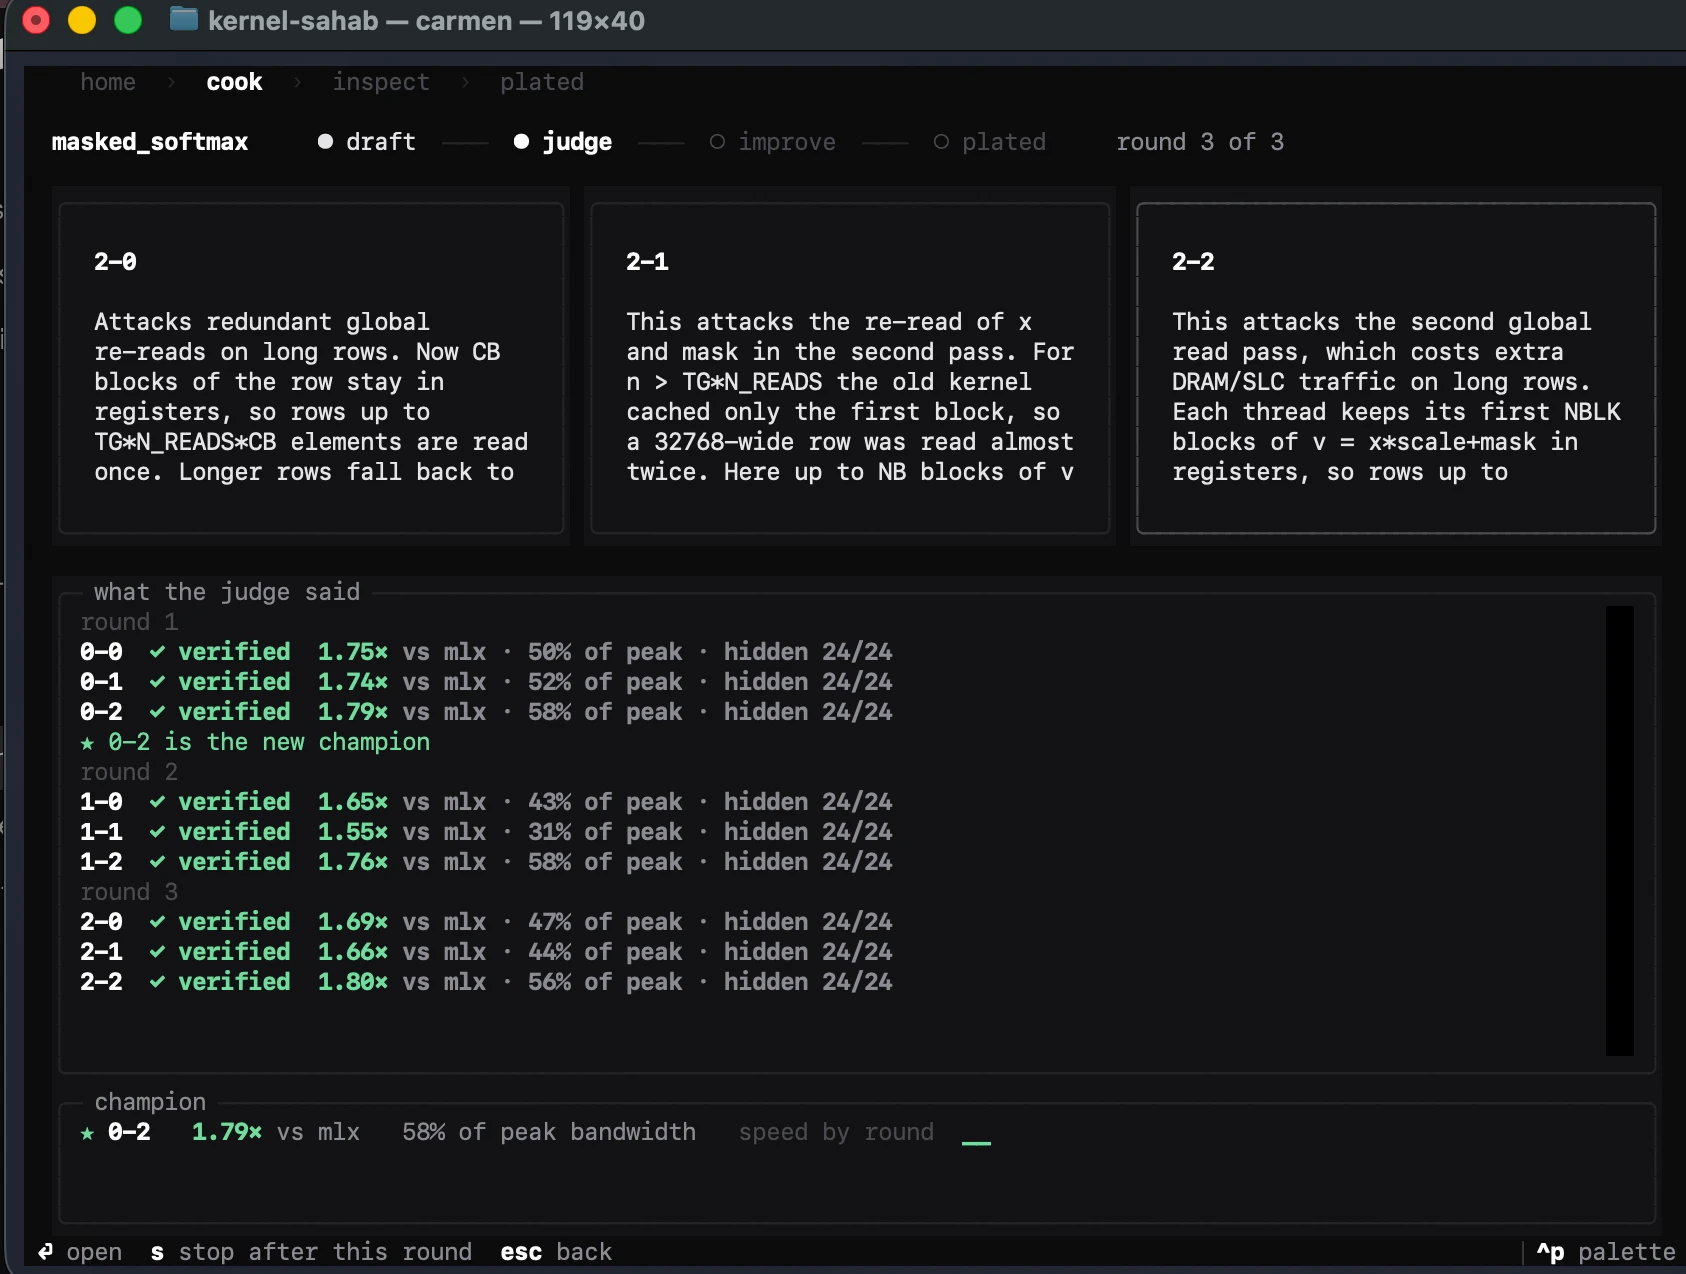
- The loop: three drafts in parallel, the best becomes the champion, the next round attacks one bottleneck. Lessons are kept only when the judge proved them.
flowchart LR
    C["Carmy × 3<br/>parallel drafts"] -->|kernel text| J{{"judge<br/>compile · float64 · invariants<br/>fresh fuzz · hidden draw · timing"}}
    J -->|"located error<br/>+ speed profile"| C
    J -->|verified & faster| K(["champion"])
    K -->|"one structural change"| C
    J -->|"proven lessons"| P[("playbook")]
    P --> C
    J -.->|"hidden results<br/>(never shown to Carmy)"| R["report"]
On an Apple Silicon Mac:
pip install carmen-kernels          # or: uv tool install carmen-kernels
carmen                              # the app
carmen speedup                      # Qwen 2.5 0.5B, stock vs carmen's kernels, on your Mac (no API key)
carmen key # only to cook new kernels: paste an Anthropic key once, saved for you only| command | what it does |
|---|---|
carmen |
the terminal app: what's proven, speed up a model, pick a kernel, watch it cook |
carmen speedup [model] |
stock MLX vs mx.compile vs carmen's bundled kernels on a real model, paired runs; no API key (--quick for ~2 min) |
carmen run <op> [--for qwen0.5b] |
let Carmy cook one kernel; --for judges it at a real model's shapes |
carmen broken <op> |
plant bugs and check the judge catches every one, next to a KernelBench-style check |
carmen judge <op> <file> |
judge a kernel you wrote |
carmen e2e [model] |
run a real model stock vs with carmen's kernels: tok/s, noise range, same answers? |
carmen profile [model] |
where a model spends its time, step by step |
carmen bench |
the feedback loop vs plain best-of-N, same budget |
From source: git clone https://github.com/utsav1033/carmen, then pip install -e '.[dev]'. Keys go in carmen key, a .env in the folder you run from, or your shell; the shell wins.
Measuring the Checker · Gaming Without an Attacker · Metal-Sci · Hacker-Fixer Loops · Test-Input Generation for Tensor Programs · Reward Hacking in Self-Improving Code Agents · Meta-Harness · Auditing Harness Tampering · SAGE · Prime Agent · KernelBench-Verified · Contract-Grade Verifier · Building a C compiler with parallel Claudes
Named after Carmen "Carmy" Berzatto. Yes, chef. Banner set in Space Grotesk and JetBrains Mono (SIL Open Font License).