


English · 简体中文
Local models: NVIDIA CUDA cu124 · AMD ROCm / Windows (experimental) · Apple MPS
Quick start · Website & resources · Installation profiles · Contribute
Amadeus is a real-time multimodal desktop agent that brings voice, character presence, and Agent work into one interface. Speak or type naturally, delegate tasks to specialized Providers, and stay involved through visible progress, permission requests, and controls to resume or take over.
The desktop app and Host run locally, with remote services or local inference selected through model configuration. Character packs are optional: Chat and Work remain available without them.
Voice assistants, desktop characters, and execution agents usually live in separate windows: one chats, one performs, and another works in a terminal or browser. Once a long task starts, it is difficult to see what is happening, which permission is needed, or whether the work can recover after a failure.
Amadeus connects those experiences into one loop:
- Talk — communicate naturally: speak or type, with interruption across generation, synthesis, and physical playback.
- Embody — make the agent present: voice, subtitles, lip sync, expression, and scene behavior share one playback timeline.
- Act — delegate real work: the main role delegates to registered Work Providers instead of receiving every tool directly.
- Control — stay in charge: Projects, Drafts, Artifacts, progress, permissions, diffs, and results remain visible and recoverable.
The character communicates and narrates, specialized Providers execute, and the Host owns identity, state, permissions, persistence, and recovery.
Important
This repository contains buildable, runnable source. This branch targets 0.17.0 Alpha, not a packaged desktop release. Amadeus first-party code is open-source under the GNU Affero General Public License v3.0 (AGPL-3.0). Third-party code and external assets retain their own terms.
Want to run it first? See Quick start. For an introduction, start with What Amadeus is trying to solve.

Click the image to watch the full 10-minute demo.
| Real-time conversation and performance | Scene-aware working state |
|---|---|
 |
 |
| Voice, subtitles, lip sync, and expression follow actual playback. | Background work drives character behavior, scene state, and result narration. |
The video demonstrates real-time voice, character performance, desktop scenes, Browser / OpenClaw tasks, and a paper-research flow. The desktop UI, Provider integration, and asset boundaries have continued to evolve, so the video is a product slice rather than a pixel-exact installation preview.
Note
The header is a brand illustration; the demo screenshots show the prototype. Characters, scenes, voices, and other third-party material in the header or demo are not granted rights by the Amadeus code license. Public source does not include character packs, model weights, reference audio, or authoring intermediates without confirmed redistribution rights.
| Area | Current public source |
|---|---|
| Interruptible real-time conversation | Shared microphone lifecycle, independent Wake / Conversation ASR, two-stage endpointing, AEC / barge-in, and interruption across LLM, TTS, and physical playback. |
| Remote Main Chat and local voice | DeepSeek V4 Flash Main Chat; Qwen3-ASR / SenseVoice; embedded GPT-SoVITS streaming synthesis (v3 by default, optional experimental v2Pro), continuous playback, and mouth values published before matching PCM windows. |
| Character and desktop presentation | SpriteForge graph state, a KTX2/PixiJS runtime, subtitle, lip-sync, and emotion timing; Chat, Work, and headless startup remain available without a character pack. |
| Provider Runtime | Pi over native RPC for daily tasks, Codex App Server / Direct Codex for complex coding, Browser for managed pages, and optional OpenClaw. Claude CLI is a committed future direct Provider. |
| Durable Work control plane | Projects, default Drafts, WorkItems / Attempts, Continue / Retry, restart recovery, permissions, the Artifact Registry, and structured diffs. |
| Artifacts and AUIP | A Work Artifact can be previewed, opened, or attached as a bounded AUIP AppSession so Amadeus can interact with it without turning narration into execution authority. |
| Unified settings | Models, Voice, Providers/MCP, vision, character-pack status, and chat appearance are managed in Electron Settings. |
MCP and Skills remain compatible-Provider capabilities even when they share a Host registry; Main Chat cannot invoke MCP tools directly. Remote DeepSeek is the Main Chat baseline; remote ASR/TTS remain explicit compatibility routes. A local voice failure never silently uploads data or creates a second billable request.
electron/       Electron main, preload, React renderer, and Settings
server/         authenticated local backend, Host control plane, and AUIP
core/           Main Chat runtime and session integration
agent_host/     Provider contracts, adapters, Work identity, and capabilities
asr/            Conversation / Wake recognition backends
tts/            synthesis backends, sentence pipeline, playback, and mouth signal
render/         SpriteForge runtime adapter and PixiJS renderer
wallpaper/      Electron/Lively hosts and Win32 desktop placement
vn_player/      experimental VN Player integration
assets/         Git-owned UI assets and external runtime-asset destinations
release/        public-source selection, provenance, and deterministic archive policy
config/         startup parsing, shared declarations in config/catalog/, state I/O
llm/            model clients, transports, and character prompt composition
characters/     built-in character definitions
sdk/            AUIP integration libraries
schemas/        machine-readable protocol and package contracts
examples/       external application and integration examples
skills/         Provider-scoped authoring instructions
tools/          maintenance and acceptance entry points (see tools/README.md)
tests/          deterministic product and boundary contracts
docs/           setup guides, contracts, and dated engineering evidence
architecture/   architecture sources and generated views
scripts/        platform launch and installation helpers
local_tts_infer.py  GPT-SoVITS inference integration used by tts/
main.py is not an application entry; it prints a retirement notice. The
Python entry is uv run --locked --no-sync python -m server.app --port 17777,
and the desktop entry is run_electron_utf8.bat on Windows or
npm run electron:dev from electron/ on macOS. Both discover .venv
automatically; choose an installation profile supported on your platform.

The dashed Memory & Persona Runtime is a roadmap extension. Its two-way connection to Main Chat represents proposed context retrieval and updates; storage, memory formation, persona updates, and lifecycle mechanisms remain to be designed.
Three separations are deliberate:
- Main Chat, Work Providers, and AUIP applications are distinct authority domains.
- A shared MCP/Skill registry does not expose those capabilities directly to Main Chat.
- Artifacts, identity, permission, and receipts are Host-verified facts; model narration cannot replace them.
Codex currently connects through App Server or Direct transport without the retired Locus gateway. Claude CLI will join the same boundary later as an independent direct Provider, not by restoring Locus.
AUIP is Amadeus's cooperative application protocol. It is not a Provider, MCP, or Main Chat tool system. It addresses a different problem: once Work has created a runnable Artifact, how can Amadeus continue collaborating with that application while preserving Host authority?
verified Work Artifact
  -> Host prepares a short-lived attach ticket
  -> application registers declared state/events/actions
  -> bounded AppSession
  -> character receives scoped projection and action receipts
- The ticket binds the current Session, an immutable Artifact reference, and a TTL. The application submits an Artifact id, not an arbitrary path.
- The Host validates workspace ownership, type, digest, and launch entry, and owns AppSession identity, revision, and action authority.
- The application may publish only declared state and semantic events and receive only declared, authorized typed actions.
- AUIP grants no
work.*,provider.*,tts.*, arbitrary filesystem, or other-Session authority. - Disconnects become visible state and invalidate pending actions instead of continuing against stale application state.
The experimental schema is amadeus.auip/v0. The protocol implementation,
Web SDK, Managed Core, application examples,
and integration tests live in this repository. See
AUIP application sessions.
Code-Amadeus/AUIP documents the current
protocol, public implementation entry points, and future SDK release criteria;
a separately versioned SDK and standalone conformance suite are not yet published.
Dependencies are grouped into four capability tiers. Start with the minimal T1
installation, then add the tiers you need. A tier is a recommended install
preset: each one is a strict superset of the one below it, and the extras
themselves encode that (vad includes voice; every local-<build> includes
vad). Platforms are not capped; the table below only recommends a tier and build
per platform. Terminology is fixed by the tier and build taxonomy.
All profiles use uv and Python 3.12; CI pins uv 0.12.8.
Linux users should start with Linux below.
| Tier | Capability | Installation |
|---|---|---|
| T1 core | Text Chat, Work, Providers, and character rendering | uv sync --locked |
| T2 voice | Remote TTS, playback, lip-sync, microphone, and remote ASR | uv sync --locked --extra voice |
| T3 vad | Real-time interruption while the character is speaking | uv sync --locked --extra vad --extra torch-cpu |
| T4 embedded | Local GPT-SoVITS, Qwen3 ASR, and wake word | uv sync --locked --extra local-<build> |
T3 and T4 need a Torch build, selected independently of the tier: torch-cpu
for T3, or one of local-cpu, local-cu124, local-cu128, local-mps, and
local-rocm for T4. The default T1 and T2 presets stay Torch-free; optional extras such as rag with
torch-cpu may still add Torch. Longer commands that also name
voice and vad remain valid and select the same environment. Optional character
RAG adds local embedding/Torch dependencies to whichever command you use.
| Platform | Recommended | Also installable | Notes |
|---|---|---|---|
| Windows + NVIDIA | T4 local-cu124 (reference) |
local-cu128 (experimental), local-cpu |
The only platform with full local-stack acceptance |
| Windows + AMD (card inside AMD's official support matrix) | T4 local-rocm (experimental) |
local-cpu |
Validation entry points under tools/rocm_sidecar/; same uv.lock and .venv |
| Linux x86_64 + NVIDIA | T4 local-cu128 (experimental) |
local-cpu |
Source deployment verified on real hardware; GPU model qualification pending |
| macOS Apple Silicon | T4 local-mps (experimental) |
local-cpu (same wheel) |
Local TTS runs on MPS; local ASR stays CPU; wake word is CPU |
| Windows / Linux without a matching GPU | T2 or T3 | T4 local-cpu |
Wake word runs on CPU; local TTS/ASR install but have no real-time promise. Set TTS_DEVICE=cpu, because auto selects cuda:0 outside macOS |
| macOS Intel | T2 | — | T3 and above cannot install: the locked Torch 2.7.0 has no macOS x86_64 wheel |
Every tier uses the same .venv. Give the complete target configuration each
time: uv sync is exact and removes packages from omitted extras.
torch-cpu, local-cpu, local-cu124, local-cu128, local-mps, and local-rocm
are pairwise incompatible; to switch builds, replace the build extra. See
installation profiles and migration.
- Main Chat defaults to remote DeepSeek. llama.cpp is an optional local LLM profile under Compatibility routes, not an installation prerequisite.
- T2 without VAD uses energy-based endpoint detection. Adding VAD enables Silero endpointing and interruption.
- On Windows, check each tier with
uv run --locked --no-sync python tools/verify_python_environment.py --profile <cpu|voice|vad-cpu>(ciis an alias ofcpu). For T4, use--profile cu124 --require-cuda-device(ort4-cpuforlocal-cpu). For ROCm, use--profile rocm, then run the GPU compute probe. Import/build checks do not replace real model and audio-device tests. - T1 is sufficient for text-only/headless use. Start the backend with
uv run --locked --no-sync python -m server.app --port 17777. SetTTS_BACKEND=disabledand disable Wake for a strict text-only profile.
T1/T2 (Windows / macOS)
- CPython 3.12, managed by uv; no system Python installation required
- Node.js 22 (
22.21.1is the current reference) - No GPU required
Additional requirements for T4 with build cu124 (Windows local models)
- CUDA 12.4-compatible NVIDIA GPU, targeting 8 GiB VRAM
- 16 GiB system RAM minimum; 32 GiB recommended
Peak memory depends on local ASR/TTS models and concurrency. The target describes the remote-Chat/local-voice profile. An optional local LLM needs additional memory according to its model, quantization, context, and GPU offload.
Install uv with winget install astral-sh.uv on Windows or brew install uv on
macOS. For T2 on macOS, install PortAudio first with brew install portaudio;
PyAudio builds from source there. Chinese step-by-step guides that cover every
feature and its external prerequisites (for example Lively Wallpaper on Windows)
are in WINDOWS_INSTALL.md, MACOS_INSTALL.md
and LINUX_INSTALL.md. Then clone and choose a tier with the same
commands on both platforms:
git clone https://github.com/Code-Amadeus/Amadeus.git
cd Amadeus

uv venv .venv --python 3.12
uv sync --locked                              # T1 core
uv sync --locked --extra voice                # T2 voice (optional)
Keep the environment named .venv. Electron discovers its interpreter
automatically (Scripts/python.exe on Windows, bin/python3 on macOS), without
requiring an AMADEUS_PYTHON override.
Build the Electron frontend on either platform:
cd electron
npm ci
npm run build
cd ..
npm ci uses the project postinstall hook to install Electron and the pinned
Pi runtime for the default daily-task agent. No separate Pi installation is
needed for desktop use. The default Pi connection reuses the same
DEEPSEEK_API_KEY configured for Main Chat under Settings -> Models or in
.env; it does not require another agent installation or login. After restart,
the backend checks the pinned runtime and selected model credentials before Pi
is advertised as available. See Pi configuration for
headless installation, native authentication, and custom model endpoints.
Where network access requires it, configure npm/Electron mirrors, such as
ELECTRON_MIRROR=https://npmmirror.com/mirrors/electron/.
Linux source deployment has been verified on real hardware. Phase 1 Linux CI (#63) has passed locked T1 + dev installation, environment imports and model-less dependency checks, basic contract tests, Ruff, architecture-view checks, and the Electron build on Ubuntu 24.04. A separate Voice source-build job checks locked installation, AEC import, bundled Abseil selection and related contracts. CI does not cover the Electron GUI, real audio devices, VAD/local model inference, Wayland sessions, or wallpaper integration. Additional jobs check cu128 candidate installation, dependencies and transitions back to T3 vad; they do not qualify real GPU model inference.
The community has reported desktop and character-rendering results on Arch Linux / Wayland. These reports do not establish compatibility across all distributions or desktop environments. See Linux tracking issue #64 for environment records, known issues, and follow-up work.
Install Git, uv (0.12.8 in CI), and Node.js 22
(22.21.1 in CI), then start with T1, which needs no GPU or voice packages:
git clone https://github.com/Code-Amadeus/Amadeus.git
cd Amadeus
uv venv .venv --python 3.12.10
uv sync --locked
cp .env.example .env
Edit .env: remove the leading # from # DEEPSEEK_API_KEY=<your-api-key>
and replace <your-api-key> with your key, producing an active
DEEPSEEK_API_KEY=... line. Leave unused providers' keys commented out.
Set TTS_BACKEND=disabled and keep WAKE_ENABLED=false to try the text-only path
first. Verify the environment from the project root:
uv run --locked --no-sync python tools/verify_python_environment.py --profile cpuBuild and launch Electron from a Linux graphical desktop session. The launcher
automatically discovers .venv/bin/python3 and starts the backend:
cd electron
npm ci
npm run build
npm run electron:dev
The desktop npm ci also installs Pi. The default Pi connection reuses the
DeepSeek credential from the base configuration and is checked when the backend
starts; custom model authentication is described in Pi configuration.
For a headless backend instead, run this from the project root:
uv run --locked --no-sync python -m server.app --port 17777For remote voice, recording and playback, install T2 in the same .venv.
On Ubuntu 24.04, install the native prerequisites used by CI first; other Linux
distributions need their corresponding package names:
sudo apt-get update
sudo apt-get install --no-install-recommends -y build-essential pkg-config portaudio19-dev
uv sync --locked --extra voice
uv run --locked --no-sync python tools/verify_python_environment.py --profile voice
For voice, local models, and desktop integration, see the component-specific notes:
- Voice / AEC: Linux uses vendored source based on the official
aec-audio-processing==1.0.1sdist and forces bundled Abseil 20240722.0 to avoid selecting an incompatible modern system Abseil. The system installation is unchanged; Windows/macOS retain their registry artifacts. Source identity, the isolated patch and removal conditions are in AEC provenance. Build/import success does not qualify real-device echo cancellation or full voice interaction. - VAD / NVIDIA: Linux T3 vad and the
local-cu128candidate have explicit Torch build selections and installation/contract CI. The cu124 reference remains Windows-specific; real GPU inference and full voice interaction require device acceptance. See the candidate profiles below. - Desktop / wallpaper: GUI and Wayland compositor integration need separate acceptance. Community GNOME results do not establish support for niri, KDE, or other desktops.
Use the same .venv as T1/T2 and select the complete capability/build combination.
T3 vad — real-time interruption: Torch enters as a CPU build.
uv sync --locked --extra vad --extra torch-cpu
uv run --locked --no-sync python tools\verify_python_environment.py --profile vad-cpu
T4 embedded — local voice models: select the CUDA profile in that same
environment. On Windows, [tool.uv.sources] routes this extra's Torch/Torchaudio
packages to the PyTorch cu124 index.
uv sync --locked --extra local-cu124
uv run --locked --no-sync python tools\verify_python_environment.py --profile cu124 --require-cuda-device
The T4 build cu124 pins torch==2.6.0+cu124, torchaudio==2.6.0+cu124, and the local
model dependencies. This is the current qualified local-model profile.
Experimental local-rocm (Windows): this profile targets GPUs in AMD's official
ROCm 7.2.1 Windows PyTorch support matrix. The same .venv can select ROCm 7.2.1,
Torch/Torchaudio 2.9.1, and the local-model dependencies. Persistent Qwen ASR and
GPT-SoVITS sidecars use that environment's interpreter by default. This profile
conflicts with cu124/CPU Torch builds. After installation, run the environment
check and GPU compute validation before loading models. See the
Windows ROCm sidecar guide for supported hardware,
installation commands, and validation steps.
Torch 2.7 profiles: local-cu128 (Windows/Linux x86_64)
and local-mps (Apple Silicon) select locked Torch/Torchaudio 2.7.0 packages.
Both are experimental: GPT-SoVITS MPS has real-hardware evidence on Torch 2.6.0
that has not been repeated on the locked 2.7.0 build, and cu128 still lacks NVIDIA
device/model qualification. Windows cu124 remains the reference, and Windows ROCm retains
AMD's 2.9.1 pair.
# Windows/Linux NVIDIA candidate, including the model dependency set
uv sync --locked --extra local-cu128
uv run --locked --no-sync python tools/verify_python_environment.py --profile cu128

# Apple Silicon MPS
uv sync --locked --extra local-mps
uv run --locked --no-sync python tools/verify_python_environment.py --profile mps
Select only the command for your platform. Installation and CPU contract CI do
not qualify GPU inference, microphones, continuous playback or interruption.
Issue #67 reports standalone Qwen-ASR MPS results on an M4 Max; the application
currently accepts only CPU/CUDA Qwen device selection. Installing local-mps
does not enable application ASR MPS routing. GPT-SoVITS supports the MPS path
through the local-mps environment.
RTX 50-series users should evaluate cu128; cu124 is not a Blackwell baseline. FlashAttention remains optional. Matching cp312/Torch 2.7/cu128 community Windows and upstream Linux wheels have been located; see Torch 2.7 and FlashAttention candidates for sources, hashes and verification limits.
The built-in Japanese Kurisu persona normally replies in at most six sentences; requests for detail or a sufficiently accurate answer may go longer. The Japanese persona override in Settings still replaces this default, and stays empty by default. This is a speaking-style rule, not a limit on report context. The latest terminal report for the Work accepted in the current conversation remains available in full for follow-up questions, including after restart. Progress updates and spoken completion reports remain brief. Provider reports retain their source and do not replace the Host's completion/verification state.
Optional character RAG is off by default and works with remote and local Main Chat. It includes a buildable Chinese/Japanese starter corpus and supports personal knowledge directories. Settings shows applied thresholds and loading state. RAG adds local embedding/Torch dependencies; the guide covers setup, diagnostics and evaluation limits.
The default local-voice profile uses the Qwen ASR and GPT-SoVITS v3 voice packs. The visual and character packs are optional:
uv run --locked --no-sync python tools\external_assets.py verify C:\Downloads\amadeus-asr-qwen3-0.6b.zip
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-asr-qwen3-0.6b.zip
uv run --locked --no-sync python tools\external_assets.py verify C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v3.zip
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v3.zip

# Optional scene and character animation (KTX2 + matching video)
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-visual-runtime.zip
uv run --locked --no-sync python tools\external_assets.py verify "C:\Downloads\amadeus-character-kurisu-2026.10.14-keypoint-return-v3.zip"
uv run --locked --no-sync python tools\external_assets.py install "C:\Downloads\amadeus-character-kurisu-2026.10.14-keypoint-return-v3.zip"
uv run --locked --no-sync python tools\external_assets.py status
The official resource center supplies
the color-corrected 2026.10.14-keypoint-return-v3 character pack, including
40 video clips (7,672 frames) and a new key-point return transition animation.
For the Google Drive download, collect all 28 parts and the helper files in one
directory, then run Assemble-Kurisu.ps1 to reconstruct and verify the full ZIP.
Do not pass an individual .zip.001 part to the installer.
To upgrade an older character pack, stop the backend and close rendering windows,
back up customized assets, then append --overwrite to the character install
command above. Old static-only packs remain supported, but do not enable the
video path. After installation, follow the recommended graphics setup and
actual-source check.
To try Kurisu v2Pro, install the separately supplied experimental add-on after the v3 voice pack. It contains the v2Pro GPT/SoVITS checkpoint pair and ERes2Net speaker encoder, and reuses the BERT, CNHuBERT, and reference audio already installed by the v3 pack:
uv run --locked --no-sync python tools\external_assets.py verify C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v2pro-experimental.zip
uv run --locked --no-sync python tools\external_assets.py install C:\Downloads\amadeus-voice-kurisu-gpt-sovits-v2pro-experimental.zip
In Settings → Voice → Voice backends → Embedded GPT-SoVITS model, select
Kurisu v2Pro · experimental under Voice checkpoint profile, then restart
the backend. For .env configuration, set TTS_VOICE_PROFILE=kurisu_v2pro;
kurisu_v3 remains the default in .env.example. Named profiles select both
checkpoints together. The embedded runtime supports v1, v2, v2Pro, v2ProPlus,
and v3 checkpoints; use custom with TTS_GPT_MODEL_PATH and
TTS_SOVITS_MODEL_PATH for another compatible pair. v2Pro/v2ProPlus also require
the speaker-encoder weight supplied in the add-on. Acceleration follows the
actual speech device and available extensions, independently of the voice preset.
v2ProPlus is also supported by the same inference pipeline, including
speaker conditioning, session caching, CUDA Graph, and streaming playback.
To use it, select Custom checkpoint pair (TTS_VOICE_PROFILE=custom) and
set the GPT and SoVITS paths to a compatible v2ProPlus pair, then restart the
backend. It uses the same ERes2Net speaker encoder as v2Pro. There is currently
no named Kurisu v2ProPlus profile or separate Plus asset pack; the experimental
Kurisu pack above contains v2Pro weights. The real-inference validation for this
change used v2Pro; v2ProPlus was not separately exercised with real weights.
If a prepared Qwen pack is unavailable, download the upstream snapshot into the same canonical location. Runtime inference remains offline and will not start an implicit download when the microphone is opened:
uv run --locked --no-sync python -c "from huggingface_hub import snapshot_download; snapshot_download('Qwen/Qwen3-ASR-0.6B', local_dir='assets/models/asr/qwen3-asr-0.6b')"The Japanese GPT-SoVITS frontend prepares an OpenJTalk dictionary on first use. Prewarm it once if the normal application launch must remain offline:
uv run --locked --no-sync python -c "import pyopenjtalk; print(pyopenjtalk.g2p('準備完了'))"These local CUDA improvements require the T4 build cu124 and
the Qwen/GPT-SoVITS assets above; T1 text, remote voice and CPU profiles do not
receive them. Keep your complete optional-extra selection when syncing
dependencies; see installation profiles.
In Settings → Voice → Conversation recognition, keep Qwen device on
auto and Qwen CUDA Graph enabled. The defaults are QWEN3_ASR_DEVICE=auto,
QWEN3_ASR_CUDA_GRAPH=true and QWEN3_ASR_FLASH_ATTN=true. Qwen acceleration
is independent of the TTS mode. CUDA Graph requires a supported NVIDIA runtime;
FlashAttention additionally needs a compatible optional extension. Unsupported
environments retain the compatible decoding/attention path. Restart the backend
after changes and check diagnostics for the actual device and inference path.
Leave Settings → Voice → Advanced voice settings → Local TTS inference mode
on Automatic (recommended). For .env configuration:
ENABLE_CUDA_GRAPH=auto
TTS_T2S_FLASH_ATTN=auto
These are also the defaults when unset. CUDA Graph automatically enables for GPT-SoVITS actually running on NVIDIA CUDA, including a GPU sidecar. CPU, MPS, ROCm and remote TTS do not automatically enable it. An NVIDIA GPU elsewhere in the host does not enable acceleration for a CPU speech runtime.
The optional FlashAttention KV-cache path is selected on NVIDIA Ampere or newer
with FP16/BF16 weights when a compatible flash-attn extension is available.
Without it, the existing PyTorch SDPA path remains active. The application does
not install extensions automatically; see optional extension installation and
verification.
T2S CUDA Graphs keep their bucket shapes while sharing one maximum-capacity KV
workspace by default (TTS_KV_CACHE_LAYOUT=nested). The existing CUDA Graph
pipeline already serializes complete TTS synthesis requests, so sharing KV does
not reduce concurrency in that mode. The decoder also holds the workspace for
an entire AR request; ordinary ASR inference and audio playback can still overlap.
Each bucket has one Graph, reused for any valid prefix length. Nested requests
promote to an already captured larger bucket when full, without copying KV;
missing targets or a full maximum bucket retain full-context dynamic fallback.
bucket keeps independent per-bucket KV and does not promote. Set the layout
before loading the model. See the nested KV
evaluation for measured memory and
latency results.
The graph and FlashAttention settings accept 0 (off), 1 (request on) and auto. Explicit values in
existing .env or desktop settings keep precedence; choose Automatic or
replace an old 0 to opt in. Manual requests still require compatible runtime
capabilities. Change the desktop mode while speech is idle; restart the backend
after changing .env or the FlashAttention setting. Startup diagnostics report
the selected path. Utterance grouping remains unchanged and opt-in.
Copy .env.example to .env (Copy-Item .env.example .env on Windows;
cp .env.example .env on macOS). In .env, remove the leading # from
# DEEPSEEK_API_KEY=<your-api-key> and replace <your-api-key> with your key.
Leave unused providers' keys commented out, then review Settings:
- Models:
deepseek, the official endpoint,deepseek-v4-flash, and an API key; - Voice: Fish Audio S2.1 + Kurisu is the recommended remote TTS profile; MiMo and OpenAI-compatible endpoints are also supported. The T4 local stack also needs a Qwen model directory, a compatible GPT-SoVITS checkpoint pair (Kurisu v3 by default or experimental Kurisu v2Pro), reference audio/text, microphone, AEC, and barge-in;
- General: optional character-pack status and presentation settings.
Launch Amadeus:
- Windows:
run_electron_utf8.bat, the shared launcher for T1–T4; it discovers.venvautomatically. - macOS:
cd electron && npm run electron:dev.
The development launcher and npm run dev use port 5173 by default. If the
terminal reports EACCES (binding denied, possibly a system-reserved port) or
EADDRINUSE (port occupied), choose an available port in the repository-root
.env, for example:
AMADEUS_DEV_PORT=15173Use a literal integer from 1 to 65535. An existing process environment variable
overrides .env; electron/.env does not configure this port. Restart the whole
launcher after changing it. Vite, Electron windows and backend origin checks
share the selected port; Electron starts only after Vite is listening. A bind
failure exits with an actionable terminal message instead of waiting forever
or silently switching ports. On Windows, inspect exclusions with
netsh interface ipv4 show excludedportrange protocol=tcp (also check ipv6).
This setting does not change the backend's port 17777.
After updating the source, run npm run build from electron/ before launching
to refresh the compiled Electron main process. Changing only the port afterwards
requires a launcher restart, not another build. Launcher shutdown asks Electron
to quit so its backend and wallpaper cleanup can finish. An invalid development
port stops the development launcher; a standalone backend logs a warning and
rejects development browser origins while retaining its native/file clients.
For wallpaper startup at macOS login, use the native Amadeus Wallpaper.app.
Build, verification, and LaunchAgent installation steps are documented in
macOS wallpaper startup.
Use Restart backend to apply after changing startup settings. A Not installed character pack is healthy and does not disable Chat, Work, or headless startup.
The default B2 AppSession action path does not block first-time setup. Chat and Settings still start without supported AUIP action-model credentials; application actions remain blocked, and Settings displays the missing capability.
VN Player needs a separately installed text extractor and a compatible game. Choose either 0xDC00 Agent or LunaTranslator and follow its setup below.
For this route, the hook script is the game's extraction .js file;
Full script for alignment is a separate, optional story-text file and can be
left empty. Amadeus does not install Agent, game scripts, or games for you.
- Download the Windows build from 0xDC00 Agent releases
and extract the whole archive. Keep
agent.exeand itsdatafolder together. - In Agent's script selector, use update scripts to obtain the
official script collection. Choose the
script matching your game's platform and version; keep its shared libraries in
data/scripts. The installation guide also explains manual installation and how to check the script first. - Enable Agent's WebSocket output at
127.0.0.1:9001, the desktop profile's expected endpoint. Close any manually opened Agent before starting it through Amadeus. Clipboard output is not used. - Open VN Player → Add game. Choose a game type, select 0xDC00 Agent, then
browse to the game's actual
.exe, its hook.js, andagent.exe. Choose Steam if the game needs Steam startup, or I will start the game for another launcher. Leave the full story script empty to begin with live text. - Click Save and test text, advance several dialogue lines, and compare the preview with the game. This test requires no model call. Once it looks right, use Text looks right — start companion. Configure the connection used by VN companion in Settings for model replies; subsequent sessions use Start.
Use the full LunaTranslator application for this route. Agent and its .js
scripts are not required; standalone LunaHook does not provide this integration's
original-text network service by itself.
- Follow LunaTranslator's official download guide,
extract the complete package, and run
LunaTranslator.exe. - Start the game. In Luna's HOOK mode, select its process, advance dialogue, and choose the text stream matching the game in the text-selection window. Confirm original text continues to arrive; see the official HOOK tutorial.
- Enable Luna's network service and note its configured port. Keep Luna and the service running while playing.
- In VN Player → Add game, select Luna original text (experimental). Set
Luna WebSocket URL to
ws://127.0.0.1:<port>/api/ws/text/origin, replacing<port>with the service's actual port. Use the original-text endpoint, not/api/ws/text/transor a web-page address. - Choose I will start the game to manage startup externally; the game executable
can then be empty. Supply the actual game
.exefor automatic exe/Steam startup or game-window vision. Full script for alignment remains optional. - Use Save and test text, advance dialogue, and compare the preview before selecting Text looks right — start companion. Capture testing makes no model calls; replies require the connection used by VN companion in Settings.
Amadeus does not launch Luna or select its hooks. End session disconnects the stream without closing Luna. See the Luna integration details.
For either source's missing text, script dependencies, and connection failures, see troubleshooting.
To use llama.cpp instead of the remote Main Chat baseline, set
LLM_PROVIDER=local, configure its executable/GGUF or an existing
OpenAI-compatible endpoint, and start it when needed:
.\start_llm_server.batManaged llama-server defaults to a 16k context and rejects insufficient capacity without truncating a Chat request. Persistent llama-cli sessions must migrate to llama-server. LM Studio and Ollama capacity behavior remains pending live acceptance. Hybrid uses its configured local HTTP first sentence plus the remote reply; it does not use the pure-local backend selector. No profile is an automatic fallback after a DeepSeek failure. The main flow is unified on Cooperative; basic and professional remain available. See Chat runtime and settings migration.
These are recommended profiles for the current APIs. They do not change the role split above, and Amadeus never switches Providers silently after an endpoint failure:
| Responsibility | Recommended profile | Current boundary |
|---|---|---|
| Main Chat API | DeepSeek-V4-Flash-0731: DEEPSEEK_BASE_URL=https://api.deepseek.com and DEEPSEEK_MODEL_NAME=deepseek-v4-flash |
deepseek-v4-flash is the stable API alias currently pointing to the 0731 release; the dated version is not used as the runtime model id. |
| Remote speech synthesis | Fish Audio S2.1: TTS_BACKEND=fish_audio, FISH_TTS_MODEL=s2.1-pro-free; Kurisu voice: FISH_TTS_REFERENCE_ID=b450b19370434173b121446057622e9b |
Bidirectional WebSocket streaming; locally committed sentence chunks use text → flush, with incremental audio output. Existing Chat sentence scheduling is preserved. |
| Multimodal / Vision | Prefer gemini-3.7-flash; use gemini-3.5-flash as a more conservative compatibility profile |
Host-owned visual context performs capture in-process, while image delivery still follows the Main Chat Provider. Independent Gemini Vision API routing is not implemented and does not imply restoring the retired Gemini Live sidecar. |
| Work execution Provider | Pi for daily tasks; Codex App Server for complex coding | Desktop installation includes the pinned Pi runtime; configure model credentials. OpenClaw remains optional for explicit selection; Browser retains managed-page operations. |
| Work execution model | Codex App Server may explicitly select a GPT-5.6-family model or deepseek-v4-flash |
The execution model belongs to the Work Provider and does not share Main Chat routing or credentials. |
| AUIP runtime action decisions | AUIP_ACTION_PROVIDER=openai, AUIP_ACTION_MODEL=gpt-5.6-terra, AUIP_ACTION_REASONING_EFFORT=low, and AUIP_ACTION_SERVICE_TIER=fast |
This model decides AppSession actions and participation; it is not the execution Provider that authors an AUIP Artifact. fast requires availability for the API project. |
After installing T2 voice, select Fish Audio under Settings → Voice → Speech synthesis, enter the API key, and restart the backend. Use:
| Setting | Recommended value |
|---|---|
| Fish inference model ID (S2.1 free model) | s2.1-pro-free |
| Kurisu voice / reference ID | b450b19370434173b121446057622e9b |
| Voice page | Makise kurisu / 牧濑红莉栖 |
| WebSocket endpoint | wss://api.fish.audio/v1/tts/live |
| Latency mode | balanced |
The equivalent local .env configuration is:
TTS_BACKEND=fish_audio
FISH_TTS_API_KEY=<your-fish-api-key>
FISH_TTS_MODEL=s2.1-pro-free
FISH_TTS_REFERENCE_ID=b450b19370434173b121446057622e9b
FISH_TTS_LATENCY=balanced
The Japanese voice ID is separate from the inference model ID. GUI credentials
use the existing encrypted store. This remote recommendation does not change the
default embedded GPT-SoVITS backend. A three-trial Windows baseline with DeepSeek
measured a 3.70 s median from chat.send to the first non-silent device write,
plus roughly 91 ms reported output latency; other networks and cold starts vary.
See Fish Audio setup, chunk probes, and audio checks.
Model weights, reference audio, character packs, and large or copyright- sensitive media are distributed separately. The source repository keeps the required icons, default wallpaper, schemas, validators, and installation tool.
Visit the Code Amadeus resource hub for available resource links and download information.
The local-voice directory contracts are asr-qwen3-0.6b and
voice-kurisu-gpt-sovits-v3, with the optional
voice-kurisu-gpt-sovits-v2pro-experimental add-on for v2Pro. The v3 pack provides
shared resources required by the add-on. visual-runtime and character-kurisu
affect scene and character presentation. See the asset bundle guide
for pack contents and installation details.
uv run --locked --no-sync python tools\external_assets.py verify C:\path\to\asset-bundle.zip
uv run --locked --no-sync python tools\external_assets.py install C:\path\to\asset-bundle.zip
uv run --locked --no-sync python tools\external_assets.py status
A bundle can be installed from any tier: external_assets.py uses only the
Python standard library. Running local voice models additionally requires the
matching model dependencies and hardware; installing a bundle alone does not
add them. See installation profiles for the qualified
cu124 profile and the ROCm experimental boundary.
A SpriteForge character package ultimately lands at:
assets/spriteforge/runtime/kurisu/
  runtime_manifest.json
  graph_config.json
  spriteforge_mouth_config.json
  textures/
The installer preserves the canonical assets/... layout, verifies SHA-256,
skips identical files, and rejects unexpected overwrites. See
external asset bundles and the
character-pack contract.
On Windows, the open-source
Lively Wallpaper is the recommended
host for Amadeus's web wallpaper. Windows opens the control panel by default
(AMADEUS_WINDOWS_STARTUP_MODE=window). Use Wallpaper in the sidebar or
change Settings → General → Startup mode to enter wallpaper directly.
When enabled, managed wallpaper mode prepares Lively 2.2.1.0, mounts the scene,
and restores the previous wallpaper on normal Quit Amadeus. --no-wallpaper
opens an ordinary window. Missing Lively is installed through winget; source
builds need .NET 8 SDK for the helper's first build. Input-surface and abnormal-exit
limitations remain tracked in #185. See the
Windows lifecycle and experiments.
Wallpaper Engine remains compatible. Set AMADEUS_WALLPAPER_HOST=external for
the original manual workflow: start Amadeus, add the URL below to Lively
(WebView2 recommended), then click Wallpaper in the Amadeus sidebar:
http://127.0.0.1:17777/wallpaper/lively/index.html
This stable entry discovers the actual asset and bridge ports automatically
and waits in place while wallpaper mode is off. Do not hard-code 17778 or
17797. For diagnostics, run
uv run --locked --no-sync python tools\run_wallpaper_engine_bridge.py and use the printed Lively URL.
See the Lively entry guide.
macOS has no corresponding Lively/Wallpaper Engine desktop host. When Wallpaper is activated, Electron hosts the full scene at the desktop level and uses a separate transparent window for the interactive Canvas. The scene remains click-through so it does not block Finder desktop icons. The macOS Electron wallpaper host has community real-device verification; dependency and CI work is tracked by #46, and signing, notarization, and an installer are not included yet.
All PixiJS character and wallpaper surfaces share one graphics profile. Configure
it in Settings → Graphics & performance, or through .env:
GUI preview (custom settings awaiting restart).

GRAPHICS_PROFILE |
Maximum frame rate | Resolution | Purpose |
|---|---|---|---|
standard (default) |
60 FPS | Native device-pixel ratio | Preserve animation quality |
power_saving |
30 FPS | Up to 1.5× | Reduce GPU use, power consumption, and heat |
custom |
RENDER_MAX_FPS |
RENDER_MAX_RESOLUTION |
Set a custom performance budget |
Custom frame rates support 10–240 FPS and resolution supports 0.25–4.0. Example:
GRAPHICS_PROFILE=custom
RENDER_MAX_FPS=45
RENDER_MAX_RESOLUTION=1.25
When Wallpaper Engine supplies a user FPS setting through
applyGeneralProperties().fps,
the runtime uses the lower of that setting and the project profile. Electron,
Lively, and other character surfaces use the project profile directly.
The GUI exposes custom FPS and pixel-density limits when Custom is selected,
preserving those values when switching presets. Saved desktop settings apply on
backend restart; reopen existing character and wallpaper windows afterward.
The page shows current backend limits separately from saved choices. Wallpaper
Engine may impose a lower FPS cap; displayed limits are not measured frame rates.
Install the matching video character pack using the asset instructions, then check these settings in Settings → Graphics & performance:
| Setting | Recommended value | Equivalent configuration |
|---|---|---|
| Graphics profile | Standard (60 FPS) | GRAPHICS_PROFILE=standard |
| Frame source | Automatic · video when available | RENDER_FRAME_SOURCE=auto |
| Frame cache budget | Automatic · video 384 MiB / static 2 GiB | RENDER_FRAME_BUDGET_MIB=auto |
| Sample animation textures | On | RENDER_TEXTURE_SAMPLING=true |
| Reuse converted textures on disk | On | RENDER_BC7_CACHE=true |
These match a fresh Standard-profile installation. Upgrading preserves explicit
choices: an old static source, fixed cache budget or disabled sampling still
takes precedence. Update those choices in Settings. For .env configuration,
use the values in the table and check configuration ownership:
desktop settings override .env, and parent-process values appear locked in the GUI.
Restart the backend and reopen the character/wallpaper. Under Actual animation frame source, the active surface should report Video with static heads · 384 MiB. If it reports Static frames, read the accompanying reason and check the matching pack/decoder; selecting Automatic alone does not prove video is active. Without compatible video assets or decoder support, Automatic retains static frames with a 2 GiB cache budget. A manually selected budget applies to both paths.
The frame budget bounds retained static-frame CPU/GPU payloads, not the entire application, voice models or decoder memory. It is not a total-VRAM cap or a guaranteed percentage reduction on every machine. See the measured comparisons and their baselines.
When not explicitly configured, texture sampling is on at a configured 60 FPS and off at other profile frame rates. Explicit on/off choices are preserved. Sampling skips source frames above the effective FPS budget while preserving required hold frames, animation duration and mouth-anchor indices. You can also enable it explicitly with the 30 FPS power-saving profile. The disk texture cache is enabled by default and targets 4 GiB of disk space; that is a disk budget.
Restart the backend and reopen the character/wallpaper after changing these
options. Changing draw FPS alone does not immediately rebuild the texture cache.
To use full-frame loading, set RENDER_TEXTURE_SAMPLING=false and restart in the
same way. The earlier 30 FPS sampling experiment
measured CPU texture buffers, not total RAM or VRAM.
Startup values use one precedence order:
- Parent-process environment variables (highest authority; shown as locked in the GUI)
- Electron desktop settings
- Repository-root
.env - Defaults in
config/settings.py
Settings never rewrites .env. Ordinary models, voice, microphones,
Providers/MCP, vision, avatars, and character-pack status belong in the GUI;
advanced diagnostics, experimental thresholds, and test-only flags remain in
.env. Secrets use the operating system's safeStorage encryption. See
configuration ownership and
local instance authentication.
| Scope | Status |
|---|---|
| T1/T2 (text + remote voice) | Source deployment on Windows, macOS, and Linux; Windows is the reference platform, with separate macOS T1/T2 and Linux CI |
| Linux | Source deployment verified on real hardware; Ubuntu 24.04 CI covers T1, T2 Voice source builds and the Electron build. See Linux setup for environment-specific notes |
| T3 vad | No NVIDIA GPU required; uses an explicit CPU build selection |
T4 with build cu124 (local CUDA 12.4 voice) |
Windows + NVIDIA; follows the qualified local-model configuration |
| AMD ROCm 7.2.1 | Targets GPUs in AMD's official Windows support matrix; local-rocm experimental profile with Qwen ASR / GPT-SoVITS sidecars. See setup and validation |
| NVIDIA cu128 | Experimental Torch 2.7.0 lock and installation CI; full device/model qualification pending |
Apple Silicon MPS (T4 build mps) |
Experimental; installed through local-mps with installation CI; TTS real-hardware evidence predates the locked Torch 2.7.0; local ASR and the wake word stay on CPU |
| 8 GiB VRAM / 16–32 GiB RAM | Target configuration; actual use depends on model selection |
| Remote DeepSeek Main Chat | First-release default profile |
| Remote ASR / TTS | Explicit compatibility path, never a silent fallback |
| Electron installer | Not provided yet; launch from source |
| macOS Electron wallpaper host | Community real-device verification; dependency/CI tracked by #46, with no signing, notarization, or installer yet |
| Docker | Not a supported desktop installation path |
| SpriteForge character pack | Externally distributed; source starts without it |
| VTS | Disabled-by-default compatibility route |
| VN Player | Experimental; installation and first text capture |
| Wallpaper hosts | Lively / Wallpaper Engine on Windows; the macOS Electron host has community real-device verification as noted above |
| PyQt / old wallpaper hosts | Retired from public mainline |
| Claude CLI Provider | Committed future mainline Provider; no live caller yet |
uv sync --locked --extra dev      # Core + dev tools; removes unselected voice/model tiers
# To retain voice/models, append --extra dev to the complete installation command
uv run --locked --no-sync python tools\verify_python_environment.py --profile ci
uv run --locked --no-sync python -X utf8 tools\run_tests.py

cd electron
npm ci
npm run build
npm audit --audit-level=high
Read CONTRIBUTING.md and ROADMAP.md before submitting a change. Product semantics, authority, protocols, Providers/MCP/Skills, Projects/Drafts/Artifacts, or AUIP changes should start with an Issue. Small fixes, documentation, tests, and presentation-only UI changes may open a PR directly. Report security issues privately under SECURITY.md.
The public repository begins with one prepared root commit. Internal development commits, experimental branches, deleted character media, models, credentials, sessions, personal paths, and original co-author metadata were not migrated. The source itself remains included according to the reviewed release boundary.
Amadeus first-party source and modifications are open-source under the GNU Affero General Public License v3.0 (AGPL-3.0). Third-party components retain their own licenses, recorded under LICENSES and THIRD_PARTY_NOTICES.md. The code license grants no automatic rights to character, model, reference-audio, or external asset packs.
- Aqua-TTS: an MIT-licensed low-latency GPT-SoVITS v3 inference runtime. Amadeus does not require Aqua to start today.
- Amadeus SpriteForge: public 0.1.0 Source Alpha for local sprite inspection, behavior-graph editing, and KTX2 character-pack preview/export. Licensed under AGPL-3.0-only; generation services are separate from the Amadeus runtime.
- Experimental extension Host profile: the implemented local-wheel TTS/MCP/Skill/theme subset, package application lifecycle, Agent binding and current limits. This is not a stable SDK or a full extension protocol conformance claim.
- AUIP: the experimental application-session / typed-action protocol implemented in Amadeus. The separate repository documents its status and public implementation entry points; a separately versioned SDK and conformance suite are not yet published.
- GPT-SoVITS: the embedded speech-synthesis inference foundation.
- OpenClaw: an optional external Work gateway.
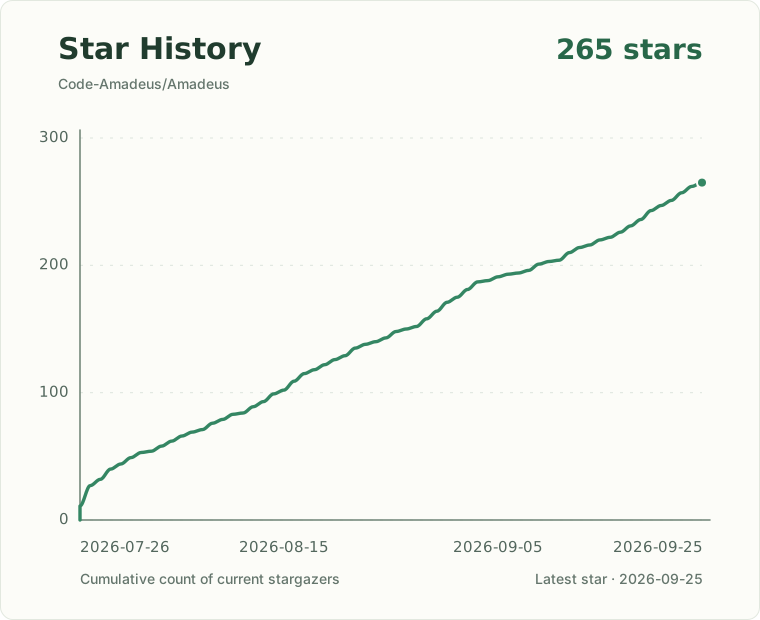
Star History